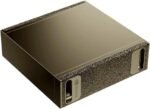
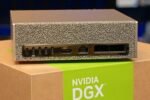
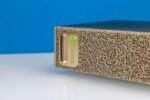
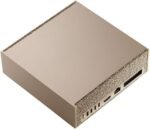
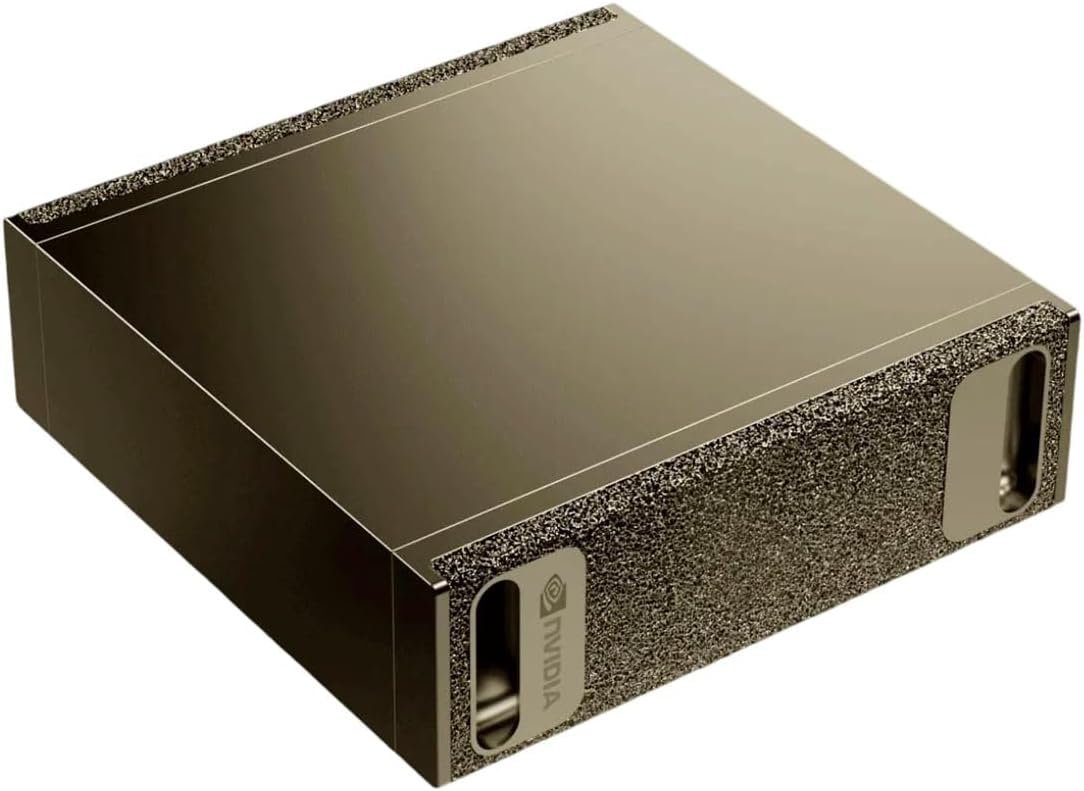
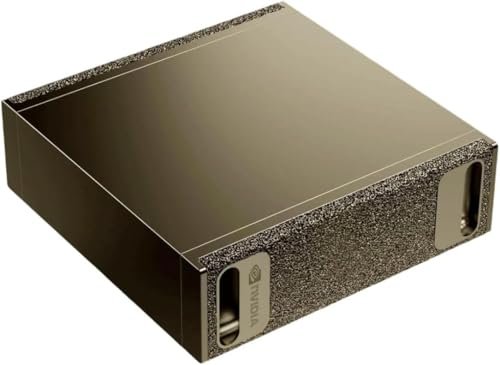
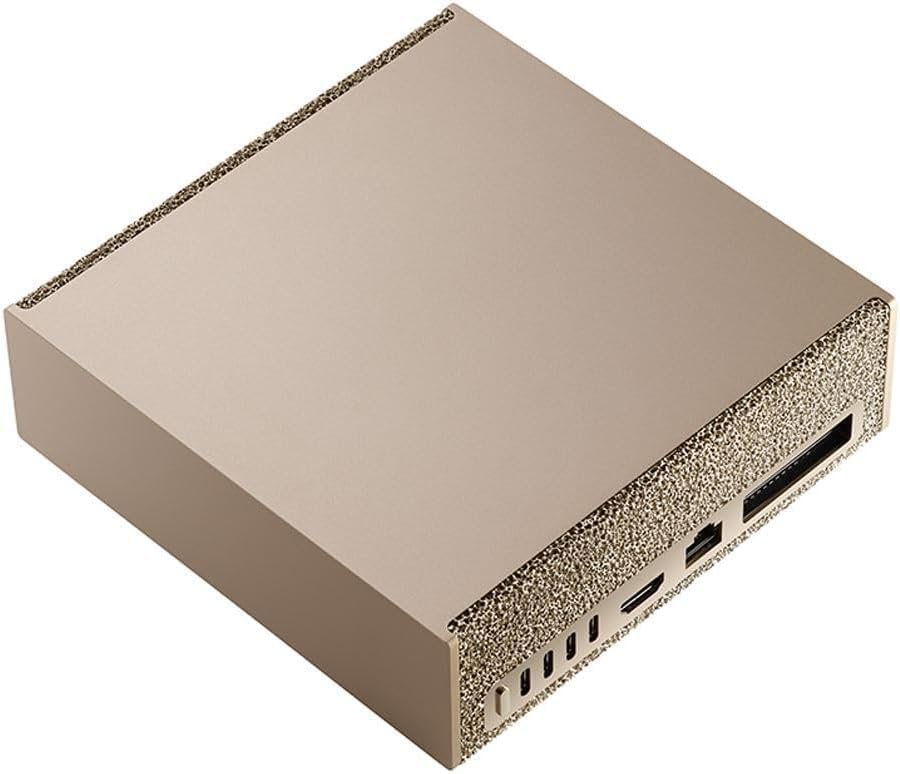
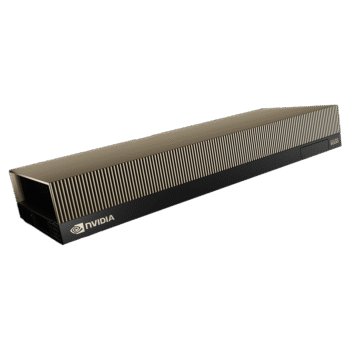
The NVIDIA DGX Spark puts data-centre-class AI compute inside a chassis the size of a hardback book, built for machine learning engineers, researchers, and small AI teams who need to prototype, fine-tune, and run large models locally instead of queuing for cluster time or metering every experiment against a cloud GPU bill. If your current workflow means spinning up an A100 or H100 instance every time you want to test a fine-tune, DGX Spark turns that iteration loop into hardware that sits permanently on your desk — no idle-GPU billing, no dataset leaving the building, and no waiting behind other researchers on shared infrastructure.
Key Features
- NVIDIA GB10 Grace Blackwell Superchip — a 20-core Arm CPU (10x Cortex-X925 performance cores + 10x Cortex-A725 efficiency cores) fused to a Blackwell-architecture GPU with 5th-generation Tensor Cores and 4th-generation RT Cores over NVLink-C2C, rated for up to 1 petaFLOP of FP4 AI compute with sparsity. This is the same silicon family NVIDIA ships in its DGX data-centre systems, scaled into a desktop form factor.
- 128GB Unified LPDDR5x Memory at 273GB/s — CPU and GPU share one coherent 128GB pool over a 256-bit memory interface, so there’s no PCIe round-trip copying data between system RAM and VRAM. This is the single biggest reason DGX Spark can hold models that would immediately run out of memory on a 24GB or even 48GB discrete workstation GPU.
- Run and Fine-Tune Models Up to ~200B Parameters — at FP4 precision, a single unit comfortably hosts models in the 70B–200B class for local inference, LoRA/QLoRA fine-tuning, and RAG pipeline development, fully offline and air-gapped if required.
- 4TB Self-Encrypting NVMe SSD — enough local headroom for multiple model checkpoints, quantized variants, container images, and full training datasets without constant shuffling to external storage.
- ConnectX-7 Smart NIC (200Gbps) — the same networking class NVIDIA deploys in its data-centre systems. Pair two DGX Spark units with a certified QSFP112 interconnect cable and pool 256GB of unified memory to run inference on models up to roughly 405B parameters.
- Full NVIDIA DGX OS + AI Stack, Pre-Installed — CUDA, cuDNN, NCCL, PyTorch and TensorFlow containers, NVIDIA AI Workbench, and accelerated frameworks such as Isaac, Metropolis, and Holoscan ship ready to use out of the box. Workloads developed here are container-portable to any other Blackwell system or DGX Cloud instance without code changes.
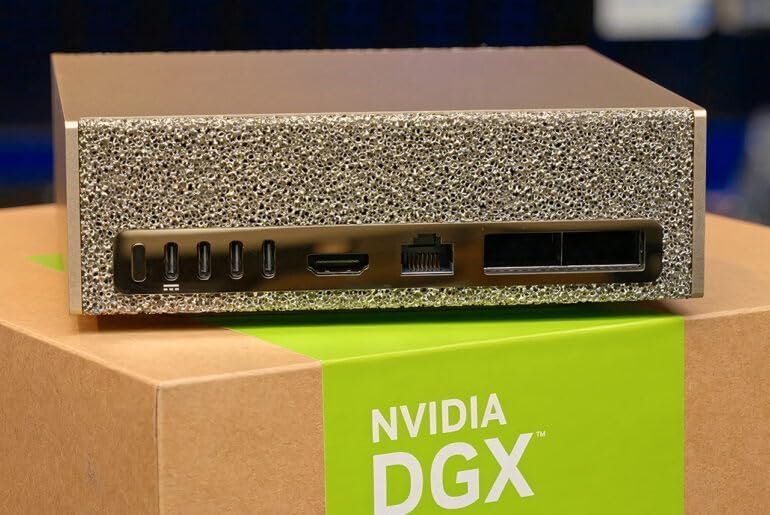
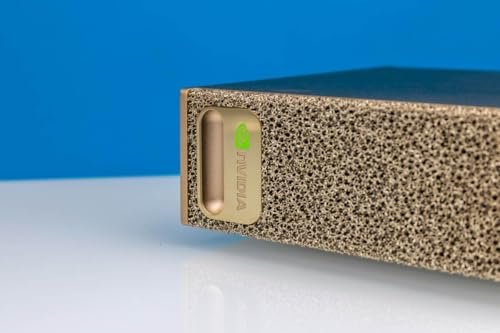
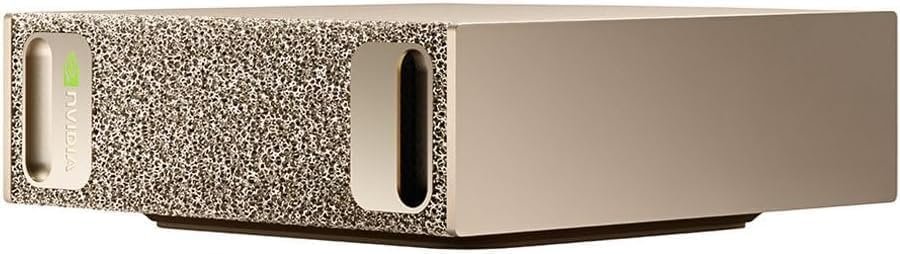
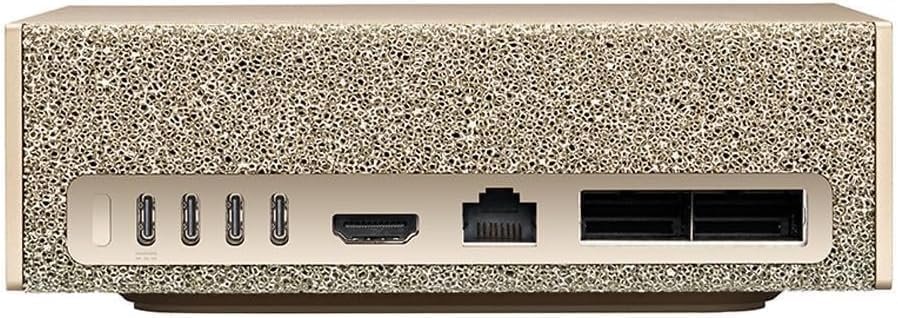
- Desktop Footprint, Data-Centre Silicon — 150 x 150 x 50.5mm and 1.2kg, powered from a single 240W supply, with 1x HDMI 2.1a and up to 3x DisplayPort 2.1 over USB-C for a full multi-monitor visualisation setup alongside training runs.
- Enterprise-Grade I/O — 4x USB Type-C, 10 Gigabit Ethernet (RJ-45), Wi-Fi 7, and Bluetooth 5.4 round out a connectivity list built for a professional desk, not a hobbyist board.
Built for Local AI Development, Not Cloud-Dependent Demos
DGX Spark exists to solve a specific, expensive problem: the gap between a laptop that can’t run a serious model and a cloud GPU bill that punishes exploratory work. Fine-tuning an open-weight 70B model, iterating on a RAG pipeline against a private document set, or benchmarking quantization strategies are all workflows that involve dozens of short, iterative runs — exactly the pattern that turns hourly cloud billing into an unpredictable monthly invoice. With 128GB of unified memory addressable by both the CPU and GPU, DGX Spark can load models that simply do not fit in the VRAM of most workstation and even many data-centre GPUs, without the complexity of tensor-parallel sharding across multiple cards.
The unified memory architecture is the differentiator worth understanding before you buy. On a discrete-GPU workstation, model weights, KV cache, and activations all have to fit inside the GPU’s own VRAM pool, and anything that doesn’t fit either gets offloaded to system RAM (with a severe throughput penalty) or simply fails to load. On DGX Spark, the GPU addresses the same 128GB LPDDR5x pool the CPU uses, at 273GB/s — so a 70B-parameter model in FP4/INT4 quantization, or a 30B model at higher precision with generous context length, loads and runs without the memory-management gymnastics that plague consumer GPU setups.
Honesty matters to this audience, so it’s worth being direct about where DGX Spark fits and where it doesn’t. The 1 petaFLOP figure is a peak FP4-with-sparsity number, and real-world dense-precision throughput on a given model will be meaningfully lower — treat it as a ceiling, not an expectation for every workload. DGX Spark is also not a from-scratch foundation-model training rig; its 273GB/s memory bandwidth and single-GPU-equivalent compute budget mean pre-training multi-billion-parameter models from random initialization is still cluster or cloud territory. Where it earns its keep is fine-tuning, quantization work, inference serving, agentic pipeline development, and computer-vision or multimodal prototyping — the day-to-day iteration loop that consumes the majority of most ML engineers’ working hours, now running entirely on hardware you own.
Because it ships on NVIDIA DGX OS — an Ubuntu Linux Pro-based distribution with the full CUDA and container stack preinstalled — the software experience is close to what you’d get on a DGX cluster or DGX Cloud instance, not a stripped-down ARM Linux port. That matters for anyone who has tried to get an unsupported ML framework working on ARM hardware before: the ecosystem here is the one NVIDIA itself maintains and ships to enterprise customers, which meaningfully de-risks the “will my stack even work” question that comes with any Arm-based workstation.
Two configurations are available: a Single Unit for teams whose model sizes fit within 128GB, and a Dual Unit + Interconnect Cable bundle — two DGX Spark units plus an NVIDIA-certified ConnectX-7 QSFP112 cable, pre-matched for clustering — for teams who want to pool 256GB of unified memory and run inference on models up to roughly 405B parameters. Choose the configuration that matches the largest model class you expect to work with over the machine’s lifetime.
Specifications
- Superchip: NVIDIA GB10 Grace Blackwell
- CPU: 20-core Arm (10x Cortex-X925 + 10x Cortex-A725)
- GPU: NVIDIA Blackwell architecture, 5th Gen Tensor Cores, 4th Gen RT Cores
- CPU-GPU Interconnect: NVLink-C2C
- AI Performance: Up to 1 petaFLOP (FP4, with sparsity)
- System Memory: 128GB LPDDR5x, coherent unified memory
- Memory Interface / Bandwidth: 256-bit / up to 273GB/s
- Storage: 4TB NVMe M.2, self-encrypting
- Networking: NVIDIA ConnectX-7 Smart NIC (200Gbps), 10 Gigabit Ethernet (RJ-45), Wi-Fi 7, Bluetooth 5.4
- USB: 4x USB Type-C
- Display Outputs: 1x HDMI 2.1a, up to 3x DisplayPort 2.1 (USB-C DP Alt Mode)
- Video Encode/Decode: 1x NVENC / 1x NVDEC
- Operating System: NVIDIA DGX OS with full NVIDIA AI software stack (CUDA, cuDNN, NCCL, container runtime)
- Max Model Size: ~200B parameters (single unit); ~405B parameters (dual-unit clustered, 256GB pooled memory)
- Power Supply: 240W (GB10 TDP 140W)
- Dimensions: 150 x 150 x 50.5mm
- Weight: 1.2kg
- Configurations: Single Unit; Dual Unit + Interconnect Cable (NVIDIA-certified ConnectX-7 QSFP112)
✓ Customer Review
★★★★★
“The equipment was exactly what I was looking for. The product
information made it easy to understand the machine before ordering.”
PRODUCT
MX-10 Mini Excavator
✓ Customer Review
★★★★★
“The product details were clear and the shopping process was
straightforward. I found exactly the type of equipment I needed.”
PRODUCT
MX-17 Mini Excavator
✓ Customer Review
★★★★★
“I liked the selection of outdoor products and the detailed
product information. Everything was easy to browse and compare.”
PRODUCT
Broil King Imperial Qs 590
✓ Customer Review
★★★★★
“The specifications were very helpful when comparing the
different graphics card options. The product page had plenty
of useful technical information.”
PRODUCT
ASUS ROG RTX 5090
✓ Customer Review
★★★★★
“There are a lot of different products to choose from, and I
appreciated having the specifications available before making
a decision.”
PRODUCT
MX-25 Mini Excavator
✓ Customer Review
★★★★★
“The computer selection gave me several options at different
price points. The specifications helped me compare the systems.”
PRODUCT
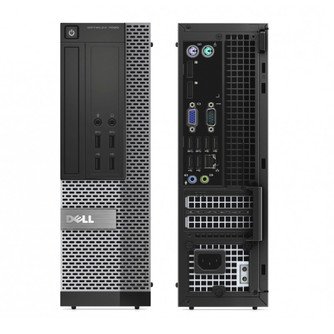
Dell OptiPlex Gaming Desktop
✓
Free Shipping
Available on eligible orders
✓
US & UK Delivery
Serving customers in both markets
✓
Customer Support
Support by email & live chat






Reviews
There are no reviews yet.